Serving Analytics to AI Agents and Human Dashboards From One Postgres View Layer
Postgres views governed for shared metrics give AI agents and dashboards one trusted source.
A governed Postgres view layer is a headless analytics backend for API-first and agent-first teams that need shared metrics without an opinionated frontend. It gives AI agents, dashboards, and pushed reports the same pre-modeled definitions and lets them read only approved data. Teams building on Supabase or Postgres can expose that governed surface to their consumers.
Why Postgres alone creates a split-consumer problem
An agent uses SUM(revenue) to report revenue, while a dashboard uses SUM(amount_captured). Both queries run on the same database without errors, but they answer different questions. The difference can go unnoticed until an investor asks for audited numbers. Nobody enforced a shared definition of revenue before those rows reached separate consumers.
With direct access, the application’s operational database also has to do the analytical work. Heavy queries can degrade production performance, while agents add connection pressure to an instance already serving mobile clients, serverless functions, cron jobs, and admin dashboards. A read replica reduces the analytical load on the operational database. But it makes the setup more complex and leaves the competing metric definitions in place. Moving a query elsewhere does not change what it calculates.
Documenting the approved query addresses only part of this problem. Every new dashboard author or agent still has to find the documentation, interpret it correctly, and preserve its logic when adapting the query. Documentation does not enforce its own rules. The resulting split is therefore both semantic and operational, with consumers independently deciding what a number means and how much access they need to retrieve it.
What a governed view layer actually is and what it must encode
A governed view layer is a set of Postgres views that encode metric definitions, entity relationships, time logic, and access policies. It places those decisions in a shared analytical surface inside or directly beside the same Postgres instance, without an extract hop. This is not a data warehouse or ETL design. The purpose is to make existing data consumable through agreed business definitions rather than through each caller’s interpretation of the storage schema.
The layer serves a semantic role as well. It translates raw schema objects into entities, relationships, metrics, and natural-language synonyms that help agents understand what they can query. Calculations such as MRR and LTV belong in this central definition layer. Time boundaries and rules for which rows can be read belong there too. A view can expose only the columns and rows a role is allowed to see, making the boundary structural rather than dependent on a caller remembering a filter.
Governance gives that structure an owner and a lifecycle. Definitions are versioned, changes are reviewed, and consumers cannot bypass the approved surface by reading base tables directly. Ownership is not an optional administrative detail. Without it, views become another collection of saved queries whose meanings can diverge. With it, the layer establishes which definitions are authoritative and how they may change.
How to structure the view layer so it serves two very different consumers
The design needs two tiers with distinct responsibilities. Fact views sit close to the source and apply column selection, type casting, and row-level filters. They insulate the analytical surface from changes in underlying tables. Metric views then compose those facts into business definitions, including the agreed treatment of events and time periods. Agents and dashboards query only the metric tier.
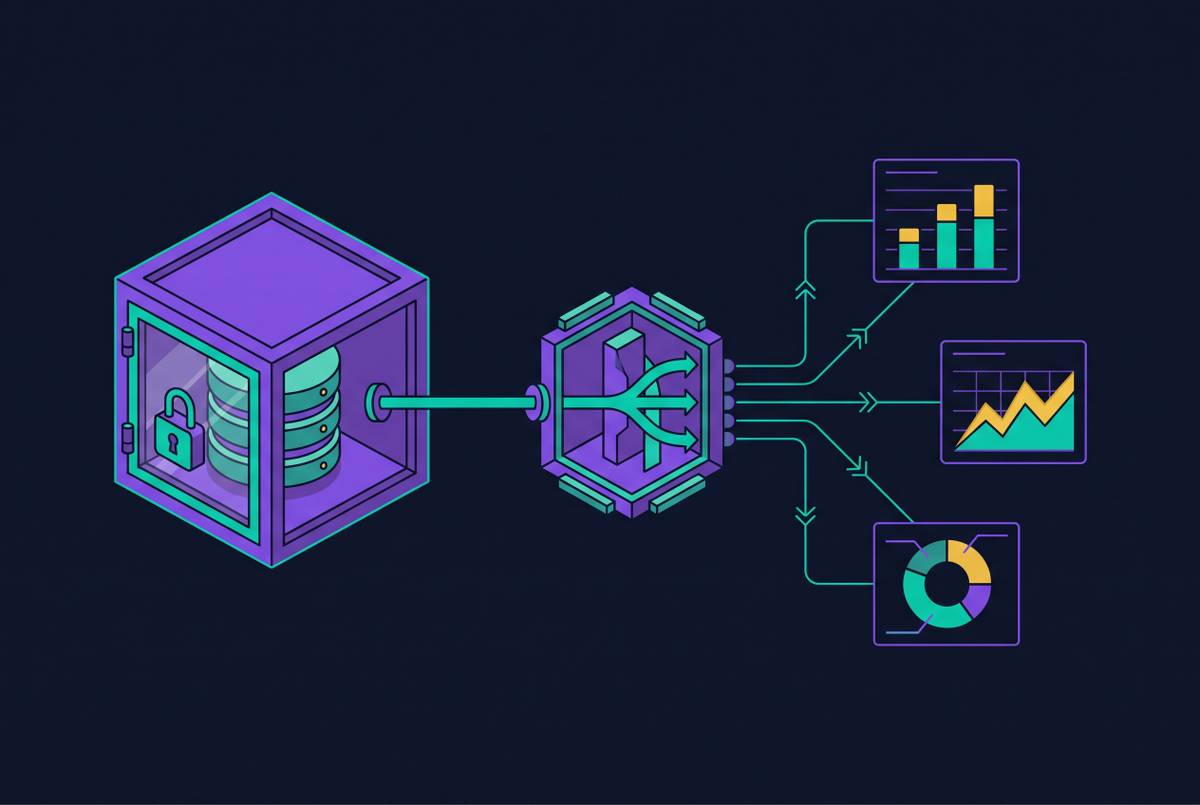
A sample schema starts with base tables that hold cancellation events and billing intervals. Thin fact views make the records from those tables available after they have been selected, typed, and filtered. A “churned subscribers” metric view joins the facts using the agreed definition of churn. The “dashboard reader” and “agent reader” roles receive SELECT only on the metric views each needs, with no agent grants on base tables or write paths. Postgres roles and row-level security set what each role can read.
Naming makes this structure easier to discover. A metric view named monthly_recurring_revenue tells a consumer what it measures, while sub_agg_v3 makes them look into how it works. For expensive aggregations, materialized metric views pre-calculate results on a refresh schedule. That introduces a staleness window, which should be documented.
Why pre-modeled definitions prevent the metric drift that breaks agent reasoning
An agent asked for MRR from raw tables must work out how to get that metric from the available schema. Its SQL may execute correctly while embodying a different definition from the one finance uses. Two agents with different system prompts can make different choices. The access pattern delegates business policy to the model at query time.
An agent and a CFO dashboard using the same metric view, with the same scope and data freshness, obtain answers from identical logic. Agents can still ask questions of the metric, but they do not need to recreate its underlying business rules to retrieve it.
Time logic makes the distinction especially concrete. Fiscal periods, trailing windows, timezone offsets, and grace periods can all change which records qualify for a metric. A “churned recently” view encodes those choices once. Without that view, each agent query must handle the same edge cases on its own, and an answer that looks right can hide a different reporting window.
Documentation remains useful for explaining why the definition exists and when it applies. It cannot, by itself, prevent another interpretation from being queried. Enforcement requires both the approved view and restricted access beneath it.
Exposing the view layer to agents safely via MCP
MCP is an open standard created by Anthropic and now governed by the Linux Foundation’s Agentic AI Foundation. It defines how agents connect to external data sources and tools, including discovering available data, understanding its schema and meaning, and querying it in a structured way. MCP supplies only the connection protocol. An MCP server pointed at the metric tier exposes the approved surface to compatible agents without a custom integration for each one.
That distinction determines what discovery should reveal. An agent asking which views are available should receive only the governed surface, while scoped database permissions keep base tables inaccessible. The protocol also has operational implications for concurrent traffic. MCP’s maintainers finalized a revision on July 28, 2026, that removed the initialize/initialized handshake and the Mcp-Session-Id header, making the protocol layer stateless. Requests can therefore go to any server instance behind a plain round-robin load balancer without session affinity.
Simpler routing does not make broad permissions safe. The State of AI Agent Security 2026 found that roughly half of production agents lacked active security or governance monitoring, with deployment outpacing governance implementation. The Open Agent Passport paper found hundreds of production MCP servers that were exposed without authentication or encryption. It also found that social-engineering success in adversarial testing was 74.6% under permissive policies and fell to zero under a restrictive declarative policy.
For Supabase and Postgres teams, direct production access introduces connection-pool pressure and the risk of bypassing row-level security. Scoped roles and metric views provide a structural boundary, though they do not remove the need to control workload. The CoSAI Agentic IAM specification recommends Zero Standing Privilege through short-lived, task- and context-bounded entitlements. A role limited to SELECT on the metric views it needs sets how much data it can read, and short-lived authorization limits how long it can do so.
What agents need from the view layer beyond query access
Approved views establish what an agent may read, but the Open Agent Passport paper explains that trustworthy operation also requires a decision about each action before it executes. Model alignment is probabilistic. Its approach evaluates declarative policy synchronously before each tool call and produces a cryptographically signed audit record. The paper measured median enforcement latency of 53 milliseconds, showing that this control can operate at the tool-call boundary.
The view defines the permitted analytical surface, while pre-action policy evaluates whether a particular request may proceed in its current context. The same boundary can also support quality gates and operational contracts. Neither control replaces the other. Restricting available views does not explain whether an agent was authorized for a particular task, and approving a task does not establish the correctness of a metric definition.
An audit also needs to show which agent acted and what data it used. The CoSAI specification treats agents as principals with their own authentication, authorization, and lifecycle, distinct from the humans they represent. Shared human credentials obscure that distinction. Versioned view definitions support reproducibility by preserving the logic used to interpret data, but reproducing an answer also requires the ability to replay what data the agent saw at that moment.
How humans consume the same view layer through dashboards and pushed metrics
A BI tool or embedded dashboard connected to the metric tier reads the same MRR, churn, and LTV definitions available to agents. It does not need a separate implementation of those calculations. Human presentation remains independent of metric ownership. This is the practical value of a headless backend for a team that wants API control without a prescribed frontend, because the analytical contract does not depend on the interface used to display it.
Materialized metric views also support scheduled delivery to Slack, email, or a mobile summary. People get pre-calculated results without having to remember to open a dashboard. When an approved definition changes, dashboards, agent queries, and pushed reports reflect it on the next refresh. Role scope and reporting context still apply. A finance dashboard, an executive summary, and an agent’s weekly report agree when they read the same definition for the same scope and period.
Building and maintaining the view layer without a dedicated data team
A technical founder can establish this pattern without first building a data engineering team. The prerequisite is discipline about defining metrics before exposing them. The initial scope can stay small. Three or four decision-driving metrics, such as MRR, active users, and churn, provide a useful starting surface, with new definitions added as consumers need them. This keeps the work tied to actual analytical questions rather than an attempt to model every table in advance.
The maintenance burden then shifts from individual queries to shared contracts. Schema versioning, access reviews, and audit log retention can be handled through infrastructure. Tooling supports that discipline but does not replace ownership. Someone still owns the definition and reviews changes, while the platform preserves the governed access pattern as more dashboards and agents arrive.
The backend needs API access independent of a prebuilt dashboard UI, a shared metric tier, role-scoped permissions, and operational support for versioning and audits. For agents to use it, the backend also needs structured discovery, verifiable identity, and pre-action authorization. These are concrete requirements. With these requirements met, another consumer can use trusted definitions, while without them it becomes another place where analytical logic is defined on its own.