Why Postgres-Native Teams Reach for a Headless Analytics Layer Before a BI Tool
API-governed metrics prevent ambiguity that BI tools alone cannot solve.
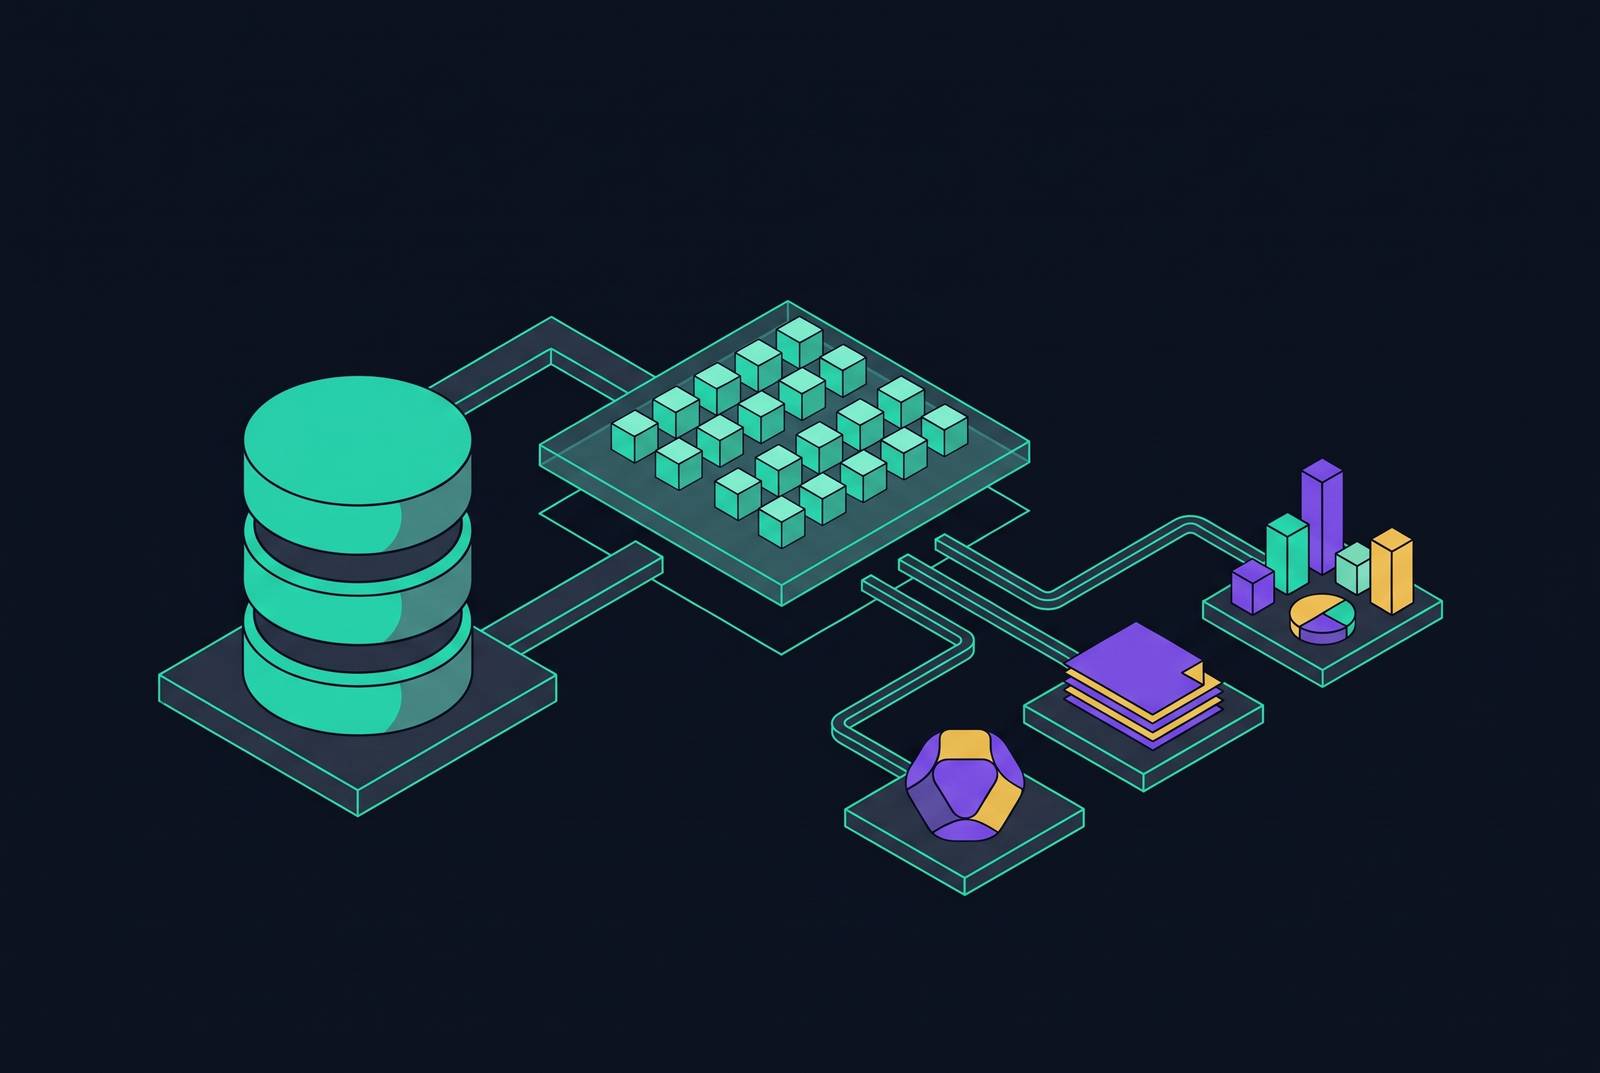
For Postgres-native teams that need full API control without an opinionated frontend, a governed headless analytics layer solves the problem that a BI tool alone cannot solve. It defines metrics once and exposes them to dashboards, applications, and AI agents through a consistent interface. The architectural priority is to settle what the numbers mean before choosing how to display them.
Why Postgres teams hit a metric definition problem before they hit a visualization problem
A founder runs SUM(revenue), while an engineer runs SUM(amount_captured). Both call the result revenue, but the numbers differ. When someone asks which is right, neither query can settle the question because each faithfully sums a different column. No dashboard has exposed the disagreement because none exists yet. The team already has a reporting problem without having a reporting interface.
Production feels like a sufficient source of truth. It records the transactions, and Postgres makes those records accessible through ad-hoc SQL. That ease of access lets a team get numbers before it has agreed on the business definitions behind them. An investor audit, board deck, or fundraise then demands a canonical figure, exposing an ambiguity that ordinary product work could leave unresolved. The team needs an agreed definition of the metric a chart would display.
What happens to metric definitions as a Postgres codebase grows
Initially, a small team can keep interpretations close through conversation. But each new engineer who works on reporting adds another place where the same terms can take on different meanings. Queries for “active user,” “conversion,” and “MRR” may all be correct against the schema without being reconciled with one another. Schema correctness does not establish business agreement. The database can enforce what a column stores, but it cannot determine which interpretation of recurring revenue the company intends to use.
The business also changes what it needs to know. At validation stage, the team mainly needs to know whether users get value and come back for more. At early traction, the team needs to know whether recurring usage is turning into steady revenue. To answer those questions, the team needs different definitions as well as different views of the same tables. As reporting expands, logic spreads across the product database, billing systems, CRMs, spreadsheets, and dashboard queries, with no canonical version connecting them.
This accumulation turns a coordination problem into an architectural one. Another conversation cannot reliably reconcile every independent query surface. Dashboard sprawl makes the disagreement visible, but its roots are in the separate definitions that each surface maintains. When finance, sales, and product each have their own version of ARR, executives must arbitrate the numbers before they can discuss the business.
Why adding a BI tool before fixing definitions makes the problem worse
A BI tool connected directly to production gives the SQL already in use a polished interface. It does not, by that connection alone, establish what the SQL should mean. A chart labeled “Revenue” reflects the calculation its author or tool supplied, even when another chart uses the same label for a different calculation. Presentation can make both versions look authoritative. Adding more tools multiplies the combinations of consumers and independently maintained definitions, giving each another opportunity to disagree.
Naming conventions do not close this gap because they are not enforced definitions. A column named revenue can be summed twelve different ways by twelve different queries. A shared name supplies no guarantee about which calculation a consumer will run. The weakness is therefore not that the chart is badly designed or the query is invalid. It is that the architecture still permits each consumer to decide what the metric means.
ClickHouse's 2026 guide documents buffer-cache contention under mixed-workload pressure, where analytical scans evict hot transactional pages from shared buffers. That contention means a monthly revenue report can slow the checkout endpoint. A read replica shifts that contention to another server, but the query plan is identical, so relocation does not make analytical queries intrinsically faster. Nor does a replica reconcile the definitions used by the tools querying it.
What analytics backend provides API control without an opinionated frontend?
A headless analytics layer defines metrics such as revenue, churn, and activation separately from the tools that display or request them. It exposes those definitions through a consistent API or query interface rather than requiring each consumer to interpret raw tables. The dependency runs in the opposite direction. Dashboards, spreadsheets, Slack bots, and AI agents become clients of a definition owned beneath them.
Enforcement is the decisive distinction between this arrangement and an API that merely exposes database access. Metrics can be pre-calculated or compiled at query time against a single definition, so a change in that definition propagates to its consumers. Serving a number is not the same as governing it. A backend that gives every client freedom to reconstruct revenue from raw columns preserves the original ambiguity, even if all requests pass through one endpoint.
For API-first and agent-first teams, the relevant criteria are therefore raw API access, definitions enforced across consumers, and independence from a prebuilt dashboard UI. Pre-calculated metrics stored in governed Parquet datasets and queried through DuckDB illustrate that separation. The analytical layer exposes the modeled output. This gives a Postgres or Supabase team a way to serve analytics without making a visualization tool the owner of its metric logic. A BI tool can then be chosen for presentation rather than for its role as an accidental definition store.
Why AI agents make ungoverned metric definitions a production risk, not just a reporting inconvenience
An agent querying production directly encounters the same ambiguity as the founder and engineer, but without a colleague to resolve the naming conflict. It can propagate whichever definition it encounters first. An agent-generated report can therefore automate a disagreement that previously remained confined to separate queries. The risk begins with the metric. Greater query speed does not help when the underlying business meaning remains unsettled.
Agent traffic also changes the operational exposure. Agents are “chatty” consumers, producing dozens of database calls per interaction rather than the predictable request-response cycle of traditional applications. Connection exhaustion and I/O contention become structural risks as concurrency grows. A read-only grant prevents writes, but it does not prevent conflicting metric definitions or analytical scans from polluting the buffer cache. The same guide identifies WAL bloat, buffer-cache thrashing, and autovacuum starvation as failure modes under this load pattern.
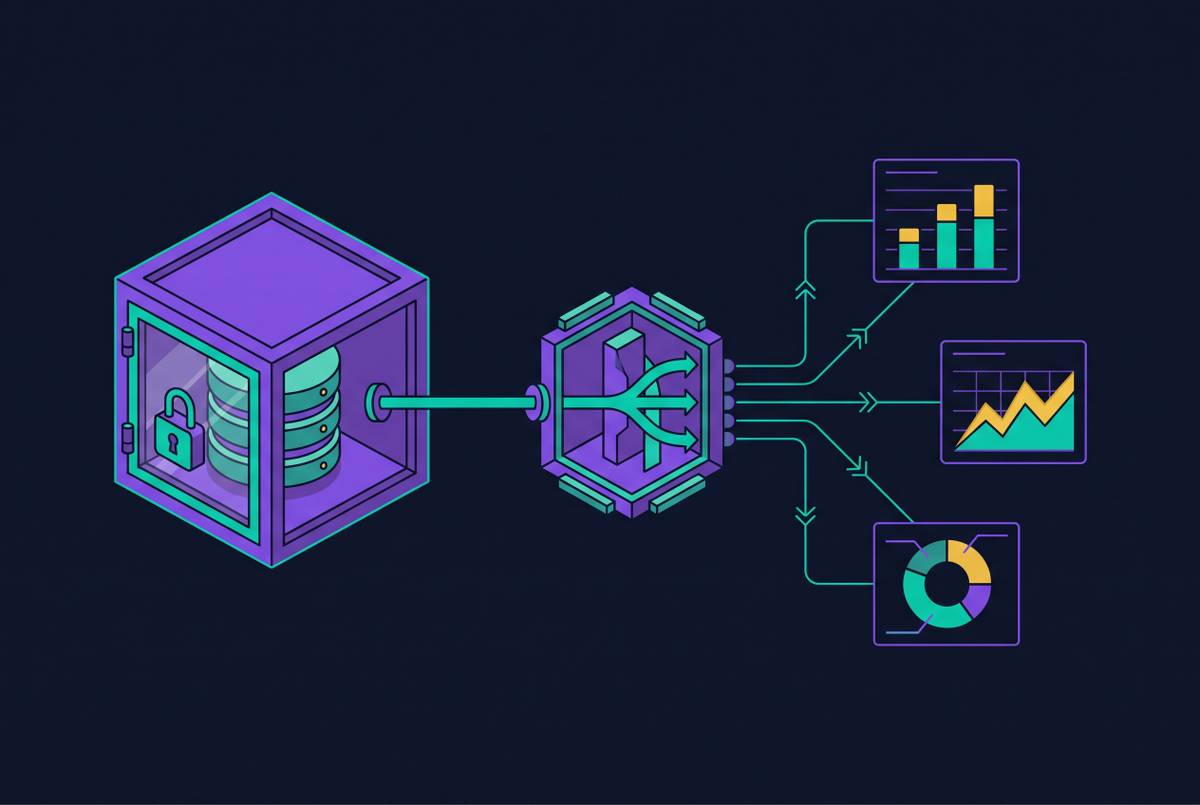
The safe architecture directs agents through a single MCP server to a governed analytical copy kept separate from production Postgres. That separation keeps analytical contention off the OLTP path while restricting agents to pre-modeled data. Protocol scalability makes this boundary more important. The July 2026 MCP specification made the protocol stateless at the protocol layer, allowing requests to land on any instance behind a plain load balancer. As agent query volume scales horizontally, a governed analytical backend gives those queries a place to go where people and automated consumers use the same definitions.
What Postgres's architectural limits mean for when to make the move
Postgres gives teams an early period in which production queries can suffice for reporting. That period ends unevenly, as workload and concurrency expose different constraints. Row-based storage creates a bottleneck for the wide-table scans and aggregations common in analytics. That storage trade-off stays in place even with tuning. So a team's transactions may run well enough even as its analytical queries compete more and more with the application for resources.
Checkout slowing during a revenue report is one such signal. Connection pool saturation shows that query complexity and concurrency are exceeding the available request capacity, while replication lag can indicate that analytical load is exceeding what a read replica was designed for. WAL growth and autovacuum starvation when high write rates combine with scan pressure are further signs of mixed-workload strain. These are diagnostic signs of a workload boundary.
Disputes over definitions are another warning sign, even when the database still performs well enough. A team that cannot get a clean investor number has already hit a limit in how it governs metrics. Teams that instrument the operational signals early can make the architectural move before a production incident forces it. For teams that do not yet need a full data warehouse, a governed analytical layer is a step between reporting from production and using a separate warehouse. It can address definitions and serving performance together without requiring a separate warehouse or ETL pipeline.
How early-stage teams build the governed layer without a dedicated data team
For an early-stage team facing these signals, the first investment should be ownership, with one person serving as the final arbiter of what CAC, MRR, and activation mean for the business. Software cannot make that business decision. Without an owner, competing interpretations can return within weeks regardless of the infrastructure used to distribute them. The owner's decisions need a layer that enforces them, and the layer needs someone with the power to make those decisions.
Begin with the handful of metrics the business actually runs on and defer the longer list that merely feels important. The team should model those metrics once in the governed layer, where changes propagate to every consumer. One interface should serve both dashboard tools and agents. An AI agent can add usage analytics without a prebuilt dashboard UI by calling governed metrics directly.
Calculated metrics can go to Slack, email, or a weekly report rather than requiring everyone to remember to visit a dashboard. For a founder unable to staff a data team, a partner who has already built and wired definitions to a Postgres or Supabase schema can take on setup and help resolve definition disputes. With an internal arbiter in place, that support lets a resource-constrained team establish the governed foundation before adding more ways to consume it.
Why BI tools work better as clients of a governed layer than as a first architectural move
Once definitions are governed upstream, a BI tool has a narrower and more useful job. It shows facts that mean the same thing no matter where they are displayed. The team can test this by checking whether replacing the tool requires rewriting metric logic. If it does, the tool still owns definitions that belong beneath it. If it does not, the team can change its visualization layer without reopening the question of what revenue means.
That independence extends beyond dashboard migrations to every new consumer. A new report or agent can use the definitions already in place without having to interpret the raw schema again. Human dashboards and agent-generated reports then agree because they share definitions, and answers to investor and operational questions come from one governed source of meaning. The reusable architectural principle is to treat the database as the system of record for transactions, the governed layer as the system of record for meaning, and the BI tool as a display surface, in that order.